


Contents
What data transparency in manufacturing actually means
Data transparency in a production environment means that the numbers people use to run the plant can be trusted — not just that they exist on a screen. Concretely: raw signals are captured automatically at the source, each data point is linked to order, product, shift and operator context, KPI definitions are the same across lines and plants, and anyone with a legitimate reason can trace a reported value — an OEE number, a scrap figure, a changeover duration — back to the underlying events that produced it.
The distinction that matters: a dashboard is not transparency. A dashboard is a presentation layer. Transparency is the chain underneath — from sensor or manual input through context enrichment and KPI logic to the figure the plant manager reads at 7:30 in the morning. If any link in that chain is missing, inconsistent or quietly edited, the dashboard gets prettier but less honest.
Why data transparency often isn't there — even when people think it is
A handful of failure modes keep transparency from happening. They rarely present as "we have no data." They present as "we have plenty of reports and somehow still argue about what actually happened last shift."
Any one of these is enough to undermine a data-driven decision culture. A plant can easily have several of them running quietly in the background at the same time.
What actually makes data transparent
Four components, in the order they matter:
- Capture at the source, automatically where possible. Machine cycles, stop events, quantities, process values via OPC UA, PLC reads, or digital I/O gateways. Manual entry is reserved for things that genuinely require a human judgement (root-cause category, rework flag), and it is structured — picklists, not free text.
- Context in one place. Each data point links to order, product, variant, shift, operator and workstation. Without context a cycle count is a number; with context it is a KPI input.
- Shared KPI definitions, centrally governed. Availability, performance, quality, changeover time, scrap — defined once, applied everywhere. This is unglamorous work and usually the single biggest determinant of whether cross-plant comparisons are meaningful.
- An auditable chain from KPI to raw event. Any headline figure can be drilled down to the underlying sequence of events. Changes to classifications are logged, not silently overwritten. This is what separates "transparency" from "a well-produced report."
In practice: the headline problem is often not missing data. It is that the numbers that exist are optimised for reporting, not for learning. The OEE posted on the wall can look healthy while the actual pattern of micro-stops, minor quality defects and unrecorded changeovers tells a very different story. None of that is malicious — it is the natural result of people being measured on a single figure and given the means to influence how it is calculated. The practical conclusion is simple: a lower but honest KPI is more valuable than a higher one you had to polish to get. A transparent data layer is the thing that makes the honest number possible.
How transparent data changes daily operations
The effects tend to show up quietly rather than dramatically. Shift handovers get shorter because there is no argument about what happened. Problem-solving sessions spend less time establishing facts and more time analysing causes. Improvement initiatives — Lean, Six Sigma, Kaizen — become easier to evaluate because before-and-after comparisons rest on the same measurement logic. Cross-plant benchmarking stops being a political exercise and becomes an operational one.
The effect on KPI numbers themselves is worth calling out honestly: when automated capture is switched on for the first time, measured OEE can come out lower than the previous manual figure. That is not the system performing worse. That is the first time the plant is looking at an unedited version of its own reality. Measurable improvement can start from there.
How the SYMESTIC platform supports the chain
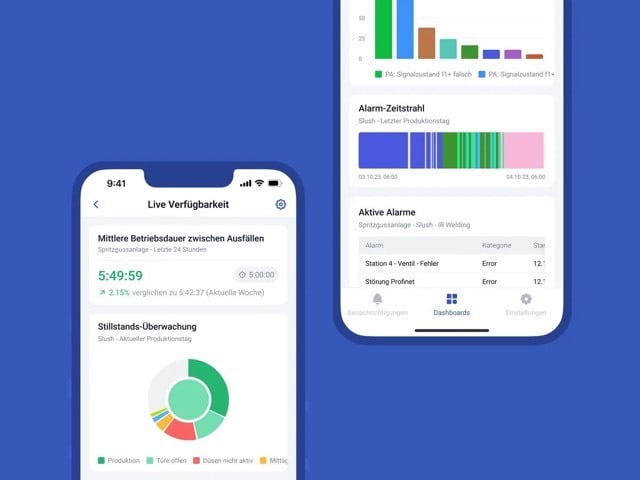
SYMESTIC is a cloud-native MES platform that covers part of the chain described above. Machine connectivity runs over OPC UA via the Cloud Gateway and, for digital signals, over the IoT Box, without intervention in the PLC. Order context can be exchanged with ERP systems (InforCOM, SAP, Microsoft Dynamics NAV, Business Central) through a documented REST API and webhooks. Production metrics capture quantities, scrap and downtimes automatically and show OEE with its availability, performance and quality components, scrap and changeover time; stop reasons are shown per machine and shift. The functions most relevant to the transparency layer are production metrics, process data, alarms and production control. They contribute to manufacturing visibility. Whether a plant needs an MES for this is the subject of 7 signs you need an MES.
FAQ
Is data transparency the same as having a dashboard?
No. A dashboard is the output. Transparency is the chain underneath — source capture, context, consistent KPI logic, traceability back to the raw events. A dashboard on top of a broken chain produces confident-looking but misleading figures.
Why do our OEE numbers drop when we introduce automated data capture?
Often because the earlier figure was based on incomplete capture, generous classification of stops as "planned", or gaps in micro-stop detection. Measured OEE can come out lower, and that can be the first honest reading the plant gets. Treat it as a new baseline, not a regression.
How is this different from manufacturing visibility?
Visibility is about seeing current state in real time across lines, shifts and sites. Transparency is about being able to trust what you are seeing — that the signals are captured correctly, classified consistently and traceable back to source. Visibility without transparency is a well-lit view of an unreliable reality.
How much of this can be done without an MES?
For a single line with one or two signals, a lot can be done with a historian, a BI tool and disciplined master-data handling. Beyond that, the combination of machine connectivity, ERP context, shared KPI logic and auditable drill-down is exactly what an MES is designed for. Plants that try to recreate it from loose components typically end up with something MES-shaped but harder to maintain.
What is the biggest risk in a transparency programme?
Starting with visualisation rather than data hygiene. If the underlying capture, classification and definitions are not in order, a better dashboard makes the problem less visible, not smaller. Investing in the chain first — even when it is the slower part — is what separates programmes that stick from ones that get quietly replaced later.
Does transparency mean exposing every number to everyone?
No. Role-based access is part of the design. Operators, shift leaders, production management and group controlling need different cuts of the same underlying data, not the same screen. The point is that all of those cuts come from one reconciled source, not from four parallel reports that happen to agree most of the time.
How does SYMESTIC handle cross-plant KPI consistency?
SYMESTIC works on a standardized data model for machines, orders, quality and plant knowledge, so the same measured values feed the figures of every plant. Whether definitions such as which stops count as planned are identical across plants is a decision the company has to make and document. Data retention, ERP integration and cloud architecture are covered in Cloud MES vs. on-premise, vendor and cost context in MES software compared. See also about SYMESTIC and pricing.
Related: MES: Definition, functions & benefits · OEE: Definition, calculation & practice · OEE software · MES software compared · Cloud MES vs. on-premise · Production metrics module · Process data module · Alarms module · Automotive · Metal processing · For COOs & plant managers · For operational excellence.
One machine. Four weeks. Your criteria.
Connect one machine and break the first silo
In a proof of value we connect one of your machines and make its data visible for four weeks against your criteria.
- Connect one machine
- Measure live for four weeks
- Check the result against your criteria
Every machine in view, even the one from 1995
SYMESTIC captures states, cycles and part counts via Plug & Play, older machines over digital signals without touching the controller.