
MES Software: Vendors, Features & Costs Compared 2026
MES software compared: vendors, functions per VDI 5600, costs (cloud vs. on-premise) and implementation. Honest market overview 2026.
MES alarm management is the discipline of capturing abnormal conditions from the shopfloor — machine faults, process deviations, quality failures, safety events — and turning them into targeted actions that reach the right person at the right time with the right information to act. The definition sounds simple; the execution is where plants routinely get it wrong, because alarm management sits on exactly the boundary between operational technology and information technology that most MES deployments underestimate. A PLC fault bit flipping high is not automatically a meaningful alarm. An operator's phone buzzing is not automatically a correct escalation. Between the fault bit and the buzzing phone lies an architectural layer that, if designed casually, produces a very common failure mode in MES projects: a system technically generating thousands of alarms per day that nobody reads, trusts, or acts on.
The alarm-management pattern that works has not changed in decades. The tooling has changed completely — COROS SCADA to OPC UA Alarms & Conditions, hardwired 24 V signal towers to MQTT Sparkplug B, desk telephones to mobile apps with geofencing — but the underlying principle holds: an alarm only earns the right to exist if a human or automated responder can do something about it. Everything else is noise, and noise trained operators to ignore signals is the worst outcome a system designed to improve reaction time can produce.
The single biggest source of confusion in alarm-management conversations is that "alarm" means four different things at four different architectural layers, and plants that treat them as interchangeable build systems where events generated at one layer never cleanly reach the layer responsible for acting on them. The four-layer model, aligned with ISA-95, keeps the responsibilities clear.
The practical implications of this separation: a PLC alarm that stays at L2 never reaches the production manager's phone; an MES alarm without a PLC source has nothing to correlate against and becomes manual data entry; an Andon signal without an MES event trail disappears the moment the tower light goes green again. The system that works is the one where events flow cleanly through all four layers — the PLC detects, the SCADA filters and annotates, the MES correlates with business context and drives workflows, the Andon provides the human-visible shopfloor signal — with each layer adding value without duplicating the layer below. Plants that collapse layers 2 and 3 into a single undifferentiated "alarm system" invariably end up with either flood (everything escalated) or silence (nothing correlated), and both failure modes cost more in downtime than the system they replaced.
The standard that most manufacturing plants outside oil-and-gas have never heard of, and that every serious alarm-management system implements whether it advertises the fact or not, is ISA-18.2 (published 2009, updated 2016; internationally harmonised as IEC 62682). It defines a ten-stage alarm management lifecycle and a state model that turns "an alarm" from a single boolean flag into a traceable workflow with deterministic transitions. Understanding the lifecycle is the difference between an alarm system that can be audited and one that cannot.
The crucial distinctions that plants without an alarm philosophy routinely collapse: Shelved is time-bounded and operator-initiated, Suppressed by Design is automatic and state-driven, Out-of-Service requires formal approval and is the only one that persists across shifts without explicit re-authorisation. The alarm system that treats these as the same state cannot explain in audit why a critical alarm did not fire on the day of a quality incident — because there is no audit trail distinguishing "operator silenced it for 30 minutes" from "engineering disabled it six months ago and forgot." Mature alarm-management deployments start from the ISA-18.2 state machine and treat everything else as implementation detail. The state machine is not decoration; it is the auditable core of the system.
EEMUA 191 (Engineering Equipment and Materials Users Association, Publication 191, "Alarm Systems — A Guide to Design, Management and Procurement," first published 1999, currently in its 4th edition) is the quantitative counterpart to the ISA-18.2 qualitative framework. It defines the numeric benchmarks that separate a functional alarm system from a dysfunctional one, and the numbers are consistent with what manufacturing plants see when the first MES alarm instrumentation is connected and the reality is baselined.
The priority distribution is the most operationally revealing metric in the table. The 5/15/80 target is not arbitrary — it reflects a human cognitive reality: an operator can only attend to a small number of high-priority events per shift. When priority inflation flattens the distribution toward 30/40/30, every alarm carries roughly equivalent visual and cognitive weight, which means the system has communicated no priority at all. The alarm philosophy exercise that precedes any real deployment must answer the question "what does 'high priority' actually mean at this plant?" before priority assignments begin, or the finished system will replicate the priority-inflation pattern of the plant's inherited assumptions.
An alarm system goes wrong in one of three characteristic ways, each with a quantifiable definition that lets you detect the problem programmatically rather than by operator complaint. Every mature alarm-management platform includes these three detectors as standard dashboard elements, because without them the system's own health is invisible to the humans running it.
Time delay, deadband and hysteresis are the three suppression techniques that eliminate most chattering in practice. Time delay (the alarm only fires after the condition persists for N seconds) handles transient spikes; typical values are 2–5 seconds for mechanical process variables, 10–30 seconds for thermal. Deadband (the return-to-normal threshold is offset from the alarm threshold) handles measurements that oscillate around a setpoint; typical deadband is 2–5% of the alarm setpoint. Hysteresis (different setpoints for entering and leaving the alarm state) combines the two for continuous analog signals. A plant that finds itself with 10–20% chattering alarms in the population is almost always missing one or more of these three at a substantial share of alarm tags, and the fix is a one-time rationalisation exercise per machine rather than a permanent operational problem.
This is the part of alarm management that the typical MES glossary entry never addresses, and the part that in real brownfield projects consumes 60–80% of the engineering effort. The capture-mechanism tree for industrial machinery, ordered from modern to legacy:
The strategic reality behind this table: most plants have a mixed fleet spanning all six mechanisms. The S7-1500 line installed in 2023 publishes OPC UA A&C events with full structured metadata; the S5-based press adjacent to it has three dry contacts wired to a terminal block that communicate everything the press is willing to say about its state. A serious MES alarm-management implementation has to normalise all six inputs into a single coherent event model at layer 3, because downstream consumers — escalation workflows, Andon, dashboards, KPIs — cannot treat the press differently from the line when business context requires the same attention. The normalisation work is unglamorous, it is where brownfield projects succeed or fail, and it is the reason why "just connect the machines" is not a statement of project scope but a decade-long engineering discipline compressed into a sentence.
Escalation without routing logic is not escalation, it is broadcast. The escalation tree that works has four design parameters that together determine whether alarms reach the right responder at the right time or fail quietly in one of several common failure modes.
The fifth parameter, often missing in first-generation escalation designs: the Andon-integration point. A physical tower light going red at the line is a signal nobody can acknowledge remotely; the supervisor who is thirty metres away looking at the line sees it first and starts walking. If the MES escalation tree does not consume the Andon state (light went red at 14:37) as input, it will either generate a duplicate escalation forty-five seconds after the supervisor is already at the machine, or it will miss the event entirely if the tower light was the only signalling channel. A well-integrated system uses the Andon state as both an escalation source (light red = alarm active) and a suppression source (supervisor physically at the machine = do not escalate further), which requires either location awareness on the operator's mobile device or a deliberate acknowledgement-at-the-machine workflow.
The alarm-management KPI that matters more than any of the standard EEMUA metrics in the context of MES — and that belongs on the standard dashboard — is the alarm-to-stoppage attribution rate: the percentage of stoppages over 60 seconds that have at least one correlated alarm event in the MES alarm log within the 2-minute window preceding or during the stoppage. The number is trivially calculable once the MES has both alarm capture and stoppage detection (via counter-stop or digital I/O), and it exposes the quality of the alarm-capture instrumentation more directly than any other metric.
The empirical pattern: plants with fully instrumented modern lines typically run attribution rates of 75–90 %; the other 10–25 % are stoppages with no alarm signal — typically operator-initiated stops, product changeovers, or mechanical faults that the PLC did not detect. Plants with brownfield instrumentation typically run 30–55 %; the majority of stoppages have no associated alarm because the capture mechanism is not seeing the fault. The gap between the two is the improvement opportunity, and it is the number that should drive investment priority. Improving alarm-capture coverage from 30 % to 70 % attribution delivers more measurable operational benefit than almost any other alarm-management investment, because it turns invisible downtime into explainable downtime and explainable downtime is the only kind that can be systematically reduced.
SYMESTIC collects the alarms of the connected machines in one place and shows them next to the downtime, so a stop and the alarms around it can be read together. The Cloud Gateway, software that runs on your own server or PC, reads alarms directly from the controller via OPC UA, including alarms that are active for only a few milliseconds. Alarms can be prioritised, and when a condition you define is met, a push or email notification goes out.
Which alarms deserve a human reaction, who acts on them and when an alarm may be taken out of service are decisions the plant makes, as the lifecycle sections above describe; the notification and downtime view supports them with data. The same downtime data feeds OEE. See also process documentation for the process definition that gives alarms their context, and change control for the governance around out-of-service transitions.
What is the difference between a PLC alarm and an MES alarm?
A PLC alarm is a raw fault bit inside the controller — motor overload, interlock violation, sensor timeout — in terms the controller understands. An MES alarm is a business-contextualised event correlated with the order, the operator, the shift and the material lot at the moment of the fault, routed through an escalation workflow defined at the manufacturing-execution layer. The two live at different ISA-95 levels (Level 2 vs Level 3) and serve different audiences: the PLC alarm drives controls engineering, the MES alarm drives production decisions. Serious alarm-management systems make both visible simultaneously without confusing them, because a plant that treats them as the same thing ends up with either flood (every PLC bit escalated to management) or silence (no business context on fault events).
What is ISA-18.2 / IEC 62682 and why does it matter?
ISA-18.2 (internationally harmonised as IEC 62682) is the management-of-alarm-systems standard published by the International Society of Automation in 2009, updated 2016. It defines a ten-stage alarm management lifecycle, formal rationalisation methodology, alarm philosophy document requirements and audit-trail expectations. It matters because it distinguishes between shelved alarms (time-bounded operator suppression), suppressed-by-design alarms (state-based automatic silencing) and out-of-service alarms (formally disabled with management approval) — three situations that behave completely differently in audit but that uninstrumented systems typically collapse into a single "silenced" category. Regulated industries (pharma GMP Annex 11, oil & gas) effectively require ISA-18.2 compliance; non-regulated industries benefit from it because the state machine is the only reliable way to make alarms auditable across shifts and operator changeovers.
What are EEMUA 191 alarm-rate benchmarks?
EEMUA 191 is the British engineering guidance document for alarm-system design, now in its 4th edition. Its key quantitative benchmarks: steady-state alarm rate below 1 alarm per 10 minutes per operator, upset-peak rate below 10 per 10 minutes, standing alarm population below 10 per operator, chattering alarms eliminated, priority distribution roughly 5% high / 15% medium / 80% low. These numbers define what a functional alarm system looks like; plants that measure for the first time typically discover they are running 5–20× above these thresholds, which is the EEMUA-predictable cause of the operator-ignores-everything failure mode. The benchmarks apply across industries — discrete manufacturing, process, batch — with only minor adjustments.
How do I prevent alarm flood in my MES?
Three techniques in descending order of impact. First, alarm rationalisation: every alarm tag justified through documented answers to the three questions "does this need human action, who takes that action, what action specifically." Second, state-based suppression during known upset conditions (startup, shutdown, changeover) where an alarm flood would otherwise be the mechanically predictable consequence of a normal operating mode. Third, root-cause bundling: when one master alarm triggers fifteen downstream consequential alarms, the MES should surface the master and suppress the consequentials. A plant starting from an unrationalised baseline typically sees alarm rates fall by 80–95 % through the first rationalisation exercise alone, without changing the underlying capture mechanism at all — most alarm flood is about what you surface, not about what the machine generates.
What is a chattering alarm and how do I fix it?
A chattering alarm is one that transitions between normal and active states three or more times within a 60-second window. It is almost always caused by a measured process variable oscillating around its alarm threshold without real change in process state — a temperature sensor at 78.5 °C when the alarm threshold is 78.0 °C, a flow rate fluctuating around its low-flow cutoff. The three fixes are time delay (require the condition to persist for 2–10 seconds before the alarm fires), deadband (set the return-to-normal threshold 2–5% below the alarm threshold so the alarm does not immediately re-fire), and hysteresis (a combination for continuous analog signals). Chattering alarms should be eliminated entirely; any chattering population above about 1% of alarm tags indicates a systematic configuration problem that warrants a rationalisation exercise rather than incremental patching.
How do I connect alarms from an old machine without OPC UA?
Three options in descending order of quality. If the machine has an S7-200/300/400 PLC without OPC UA, a direct-read connection via S7 protocol to the fault-bit data blocks works reliably — requires coordination with the controls engineer to document which bits carry which meaning, but otherwise produces clean boolean events. If the PLC is inaccessible or pre-dates S7 (Simatic S5, or equivalent from other vendors), a digital I/O gateway connected to the machine's hardwired 24 V status outputs captures the boolean transitions without any PLC contact. If the machine has neither accessible PLC nor hardwired status outputs, counter-derived synthetic alarms work as the fallback — a cycle counter that stops for more than 120 seconds is a synthetic fault even if the machine itself is not reporting the condition. All three approaches are standard brownfield techniques; the choice is about what the machine is willing to say, not about what would be theoretically ideal. The MES normalises the output into a uniform event model regardless of the capture mechanism.
How does MES alarm management relate to Andon?
Andon is the physical visual/acoustic signalling layer on the shopfloor, originally from Toyota Production System, used to communicate machine state to humans in the immediate vicinity. MES alarm management is the systems-level event-correlation and escalation layer that operates at ISA-95 Level 3 with business context. The two are complementary, not competing: Andon communicates to the humans near the line, the MES communicates to the humans responsible for the line who may be elsewhere in the plant or off-shift. The integration point is that Andon state (tower light colour, board message) should feed into the MES as both an escalation input (light red = alarm active, start the workflow) and an escalation suppression input (supervisor physically present at the line = do not escalate further to plant management). A system that treats Andon as a parallel disconnected layer produces duplicate escalations and missed events; a system that integrates them improves the signal-to-noise ratio considerably.
What is the alarm-to-stoppage attribution rate?
The percentage of machine stoppages over 60 seconds that have at least one correlated alarm event in the MES alarm log within a 2-minute window around the stoppage. It is the KPI that directly measures how well your alarm capture reflects the actual downtime of the plant: a stoppage with no correlated alarm is invisible downtime, which is also unimprovable downtime because nobody can fix what nobody can see. Modern fully instrumented lines typically run 75–90% attribution; brownfield-instrumented plants typically run 30–55%. Improving attribution rate from the brownfield baseline toward the modern baseline is usually the highest-ROI alarm-management investment a plant can make, because every percentage point turns invisible downtime into explainable downtime that can be attacked with root-cause analysis and process improvement.
Related: MES: definition, functions & benefits · OEE: definition, calculation & practice · MES software compared · OEE software · Process documentation · Predictive quality · Change control · Role-based access control · Schedule adherence · On-Time Delivery · Rolled Throughput Yield · Scrap rate vs. rework rate · Recipe management · Alarms module · Process data module · Production metrics module · Automotive · Metal processing · Food & beverage · Plastics processing · For maintenance managers · For production managers · For operational excellence. External references: ISA-18 Alarm Systems Management committee (ISA-18.2 / IEC 62682) · EEMUA Publication 191 · OPC Foundation — OPC UA (Part 9: Alarms & Conditions).
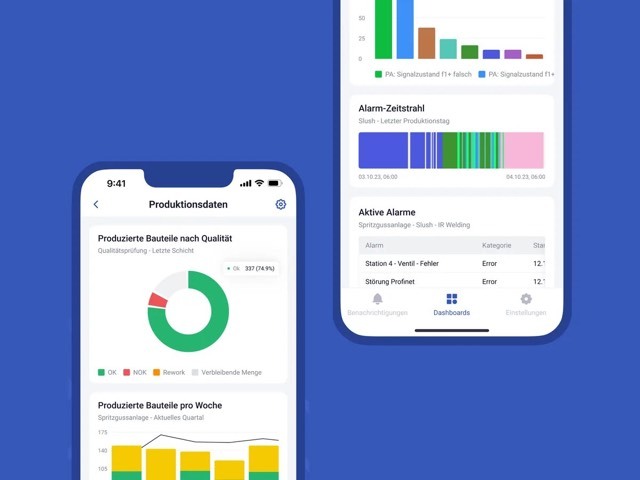
Machines report plenty. Which alarm actually stopped the line, nobody can say afterwards.
See machine alarms centrally and trace them to the cause
SYMESTIC collects the alarms of all machines in one place and puts them next to the downtime. When a condition you set is met, you get a push or email notification.