


Contents
What is Mean Time To Repair (MTTR)?
MTTR (Mean Time To Repair) is the average time from the moment a machine fails to the moment it is back in production. If a press line experienced 8 unplanned failures in a month and the total unplanned downtime was 40 hours, the MTTR is 5 hours per failure. MTTR measures maintenance efficiency — how fast your team restores a machine after it breaks. It is the complement of MTBF (how often a machine breaks). Together, they define OEE Availability: Availability = MTBF / (MTBF + MTTR). You can improve Availability by increasing MTBF (failing less often) or decreasing MTTR (repairing faster).
Calculate MTTR directly: MTBF/MTTR calculator
How do you calculate MTTR?
MTTR = Total Unplanned Downtime / Number of Failures
Where:
- Total Unplanned Downtime = the cumulative time the machine was not producing due to unplanned failures. Starts when the machine stops, ends when the first good part comes off the line.
- Number of Failures = count of unplanned stops requiring maintenance intervention. Planned maintenance, changeovers and operator breaks are excluded.
| Worked example — Press line 3, March 2026 | Value |
|---|---|
| Unplanned failures in the month | 8 |
| Total unplanned downtime | 40 hours |
| MTTR (40 / 8) | 5.0 hours |
| Total operating time (after subtracting all downtime) | 400 hours |
| MTBF (400 / 8) | 50 hours |
| Availability (50 / (50 + 5)) | 90.9 % |
The number 5.0 hours is the average. Averages hide reality. If 6 of the 8 failures took 2 hours each and 2 failures took 14 hours each, the average is 5 hours — but the problem is not "repair takes 5 hours." The problem is "two catastrophic failures took 14 hours each." An MES that shows the full distribution of repair times — not just the average — tells maintenance managers where to focus.
What are the 5 phases of repair time — and where is the real waste?
MTTR is not "wrench time." The 5 hours between machine stop and machine restart contain 5 distinct phases. Most of the time is not spent repairing. It is spent before and after the repair. Understanding this breakdown is the key to reducing MTTR.
| # | Phase | What happens | Typical share of MTTR | How the MES makes it visible |
|---|---|---|---|---|
| 1 | Detection | The time between the actual failure and someone noticing. On night shift, a machine can stand idle for 15–45 minutes before anyone reacts. | 5–20 % | MES detects the stop instantly from the machine signal and sends a notification to the shift lead and maintenance. Detection time drops to near zero. |
| 2 | Diagnosis | The maintenance technician arrives, assesses the situation, identifies the root cause. "Is it the motor, the sensor, the hydraulic valve, or the PLC program?" | 15–35 % | MES alarm history shows the exact alarm code, the sequence of alarms before the failure, and the process parameter trends (pressure, temperature) leading up to the stop. SPS alarm correlation cuts diagnosis time by eliminating guesswork. |
| 3 | Logistics | Waiting for the spare part, the tool, the specialist, the forklift, the approval to shut down a connected system. Often the longest phase. | 20–40 % | MES data shows which alarm codes lead to long logistics waits. If alarm #3012 always requires a bearing that takes 3 hours to procure, the countermeasure is spare-part stocking — not faster wrench work. |
| 4 | Repair (actual wrench time) | The physical repair: replacing the part, adjusting the setting, fixing the wiring. | 15–30 % | MES timestamps mark when the machine state changes from "maintenance active" to "startup." Comparing repair duration across technicians identifies training needs. |
| 5 | Restart & verification | Restarting the machine, running test parts, verifying quality, ramping up to full speed. | 10–20 % | MES cycle time analysis shows how long until the machine reaches normal cycle time after restart. If restart takes 45 minutes on press 3 but 15 minutes on press 4, the startup procedure is the variable. |
The insight that changes everything: actual repair (phase 4) is typically only 15–30 % of total MTTR. The rest is detection, diagnosis, logistics and restart. Faster wrench work is not the answer. Faster detection (MES notifications), faster diagnosis (MES alarm history), and smarter logistics (MES-driven spare-part strategy) are the answers.
How does MTTR compare to MTBF, MTTF and other maintenance metrics?
| Metric | Full name | Measures | Drives improvement in |
|---|---|---|---|
| MTTR | Mean Time To Repair | How fast you fix failures | Maintenance efficiency → OEE Availability |
| MTBF | Mean Time Between Failures | How often failures occur | Equipment reliability → OEE Availability |
| MTTF | Mean Time To Failure | Lifespan of non-repairable components | Spare-part strategy, preventive replacement timing |
| MTTA | Mean Time To Acknowledge | How fast someone responds to the failure alert | Detection phase (phase 1 of MTTR) |
| MDT | Mean Down Time | Total downtime per failure (includes administrative delays, not just repair) | Overall downtime management |
The relationship that matters most: Availability = MTBF / (MTBF + MTTR). With MTBF = 50 h and MTTR = 5 h, Availability = 90.9 %. To reach 95 % Availability, you can either increase MTBF to 95 h (difficult — requires reliability engineering) or reduce MTTR to 2.6 h (often faster and cheaper — requires better detection, diagnosis and logistics). Most plants should attack MTTR first because the improvements are faster and require less capital.
Why is manual MTTR tracking unreliable — and how does an MES fix it?
MTTR has the same data quality problem as MTBF: the inputs are theoretically simple but practically unreliable when tracked manually.
- "When did the machine actually stop?" The maintenance log says 10:30. The MES says 10:17. The operator noticed at 10:30 — the machine had been idle for 13 minutes. Those 13 minutes are detection time (phase 1), but in the manual log they are invisible. The MES timestamps the machine-state change at PLC resolution — the true stop time, not the discovered-stop time.
- "When was the machine actually back in production?" The maintenance log says "repair completed at 14:00." The MES shows the first good part at 14:38. The 38 minutes of restart and ramp-up (phase 5) are invisible in the manual log. The MES captures the actual moment when normal production resumes — the true end of downtime.
- "What was the failure?" The maintenance log says "hydraulic issue." The MES alarms module says "alarm #3012 — hydraulic pressure below 180 bar, preceded by alarm #3008 — oil temperature above 65 °C, preceded by alarm #3005 — cooler fan current below threshold." That sequence tells maintenance the root cause is the cooler fan — not "a hydraulic issue." SPS alarm correlation turns vague failure descriptions into precise root-cause chains.
- "How long did each phase take?" Manual logs capture total downtime. They do not break it into detection, diagnosis, logistics, repair and restart. The MES — combined with operator acknowledgement timestamps — can decompose total MTTR into its 5 phases per failure event. That decomposition is where the actionable improvement lives: "Our average MTTR is 5 hours. 40 % of that is logistics wait. The top spare part causing the wait is bearing type SKF-6205. Stocking 10 units on site would cut MTTR to 3 hours."
The SYMESTIC production metrics module calculates MTTR automatically from machine-state data: every stop event with start time, end time, duration and alarm code — per machine, per shift, per week. The maintenance manager sees not just the average, but the distribution: "Machine 5 had 8 failures. Six were repaired in under 2 hours. Two took 14 hours each. The two long repairs were both alarm #3012. That is the priority."
How do you reduce MTTR in practice?
| MTTR phase targeted | Action | Typical MTTR reduction | MES role |
|---|---|---|---|
| Detection | Automatic MES stop notification to shift lead + maintenance via push or email | Detection time → near zero | MES detects stop from PLC signal, sends notification within seconds. Digital machine signals provide instant stop visibility. |
| Diagnosis | MES alarm history displayed on shopfloor screen: alarm sequence, frequency, last occurrence, last fix applied | Shorter diagnosis time | Technician sees the alarm chain before arriving at the machine. No guesswork. Alarm correlation makes root causes self-evident. |
| Logistics | MES data drives spare-part strategy: stock parts that cause the longest waits, pre-stage tools for recurring alarm codes | Shorter logistics time | MES Pareto shows which alarm codes lead to the longest total downtime. Cross-reference with spare-part availability reveals stocking gaps. |
| Repair | Standardise repair procedures for top 10 alarm codes. Train based on MES data showing repair time variance per technician. | Repair time −10–20 % | MES shows repair duration per alarm code per technician. If technician A repairs #3012 in 90 minutes and technician B takes 4 hours, the gap is a training opportunity. |
| Restart | Standardise startup sequence. Document parameter settings for each product. Pre-heat where required. | Restart time −15–30 % | MES cycle time analysis shows time from machine start to first part at normal cycle time. Variation across shifts/operators reveals non-standard restarts. |
FAQ
What is a good MTTR value?
There is no universal benchmark — MTTR depends on machine complexity, spare-part availability, maintenance team size and shift coverage. A 30-minute MTTR on a simple conveyor is normal; a 30-minute MTTR on a 200-tonne hydraulic press would be exceptional. The meaningful benchmark is internal: your machine's MTTR this month vs. last month, and your MTTR by alarm code. If alarm #3012 takes 8 hours and alarm #4001 takes 20 minutes, improving the #3012 response is where the value is — and MES data shows exactly that.
Should I focus on reducing MTTR or increasing MTBF?
Both — but MTTR improvements are typically faster and cheaper. Increasing MTBF (fewer failures) requires reliability engineering: better components, preventive maintenance, design changes. Reducing MTTR (faster repair) requires better information, better logistics and better procedures. The MES provides the data for both: MTBF trend shows whether your reliability programme is working; MTTR breakdown shows where your repair process is wasting time. Start with the metric where the data reveals the bigger gap. If most downtime comes from a few long repairs, attack MTTR. If downtime comes from many short failures, attack MTBF.
How does MTTR relate to OEE?
MTTR affects the Availability factor of OEE through the formula Availability = MTBF / (MTBF + MTTR). Cutting MTTR from 5 hours to 2.5 hours with the same MTBF of 50 hours improves Availability from 90.9 % to 95.2 %. On a line running 480 hours/month, that 4.3-percentage-point improvement translates to approximately 20 additional production hours — pure capacity gain with zero capital investment.
Can MTTR be too low?
Yes — if it is achieved by rushing repairs. A technician who fixes a hydraulic leak in 20 minutes by tightening a fitting without replacing the degraded seal achieves a low MTTR for that event — but causes the same failure to recur 48 hours later, increasing failure frequency and worsening MTBF. The goal is not the fastest repair. The goal is the fastest correct repair. MES recurrence analysis shows this: "Alarm #3012 was resolved 4 times in 14 days. The first 3 repairs were under 30 minutes. The 4th took 6 hours because the root cause was finally addressed." That pattern exposes the rushed-repair problem.
Related: MTBF (Mean Time Between Failures) · OEE Explained · TPM · Predictive Maintenance · SYMESTIC Alarms Module · SYMESTIC Production Metrics · MES: Definition & Functions
Calculate what your repair times cost
In a free 30-minute call we take your failures and repair times and calculate what downtime costs you per year.
Know why the line stopped, not just for how long
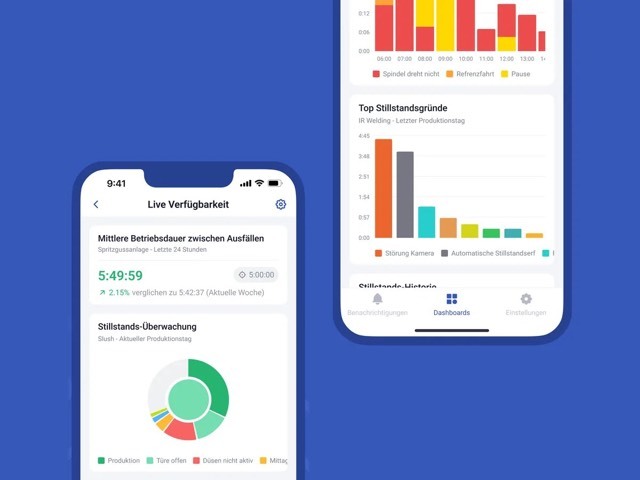
SYMESTIC detects every stop at the machine, and the operator picks the reason. Meleghy Automotive cut downtime by 10% with SYMESTIC.
−10%downtime
Automotive supplier cut downtime by 10%
Meleghy Automotive also raised output by 7%. Started on one press line, SYMESTIC ran in all four plants six months later.