


Contents
What are downtimes?
Downtimes are the individual events in which a production asset stops producing good parts while it was scheduled to run. Plural matters here: a single day rarely has one downtime — it has dozens or hundreds of stop events, each with its own cause, duration, response time and cost tail. Understanding downtime as a distribution of events, not as a monthly aggregate, is the single most important shift in how operations teams improve availability.
This article deliberately takes a different angle from the related Machine Downtime entry. That one covers the taxonomy — planned vs. unplanned, micro-stops, MTBF, how to capture events automatically. This one covers what happens after a stop starts: how the plant notices, how people respond, how the line recovers, and how much each of those steps actually costs. The measurement side has improved dramatically across the industry. The response side has barely moved.
Calculate what downtime costs you per hour
The operational truth: most downtime losses are not caused by the stop itself. They are caused by the delay between the stop starting and the right person standing in front of the machine, and by the "recovery tail" that follows every restart — the period during which the process is running again but not yet producing at nominal quality or speed. Both are invisible in ERP reports and in most OEE dashboards.
The anatomy of a single downtime event
Every downtime event, regardless of cause, passes through the same five phases. Each phase has a different owner, a different lever and a different typical duration. Plants that improve availability dramatically are almost always the ones that measured all five — not just the middle one.
| Phase | What happens | Owner | Typical duration |
|---|---|---|---|
| 1. Detection | The stop is recognised as a stop — not just a pause | Operator or automatic system | 0 s (MES) to several minutes (manual) |
| 2. Notification | The right responder (operator, maintenance, supervisor) is alerted | Andon / escalation architecture | 30 s to 15 min |
| 3. Diagnosis | The responder identifies the actual cause | Maintenance, operator | 1 to 30 min |
| 4. Repair / correction | The fault is fixed, the machine is ready to run | Maintenance | 2 min to several hours |
| 5. Recovery | Machine is running again but not yet at nominal speed / quality | Operator, process | 30 s to 20 min |
Most plants measure Phase 4 — the "repair time" — and call that the downtime. The honest number is Phases 1 through 5 together. When automatic capture is installed for the first time, the delta between what the plant thought its downtime was and what it actually was is routinely large. Not because anyone is lying, but because Phases 1, 2 and 5 are invisible without data.
The hidden half: detection and notification delays
Phases 1 and 2 — detection and notification — are where the first, silent loss happens. A machine in a high-volume line that stops at 14:27 and is only noticed by the shift supervisor at 14:41 has already lost 14 minutes before anyone started trying to fix anything. Those 14 minutes are attributed to "repair time" in the end-of-shift report, which is why the plant concludes it has a maintenance problem when it actually has a notification problem.
| Notification method | Typical delay to right responder | Blind spot |
|---|---|---|
| Operator notices, walks to supervisor | 3–15 min | Operator absent, busy with another line, no clear escalation path |
| Andon light / button | 30 s – 5 min | Only effective when someone actively watches the light |
| MES with automatic stop detection & mobile alert | 10–60 s | Only missing when mobile coverage or escalation rules are incomplete |
| ERP-based tracking (next shift) | Hours to a full shift | Useless for response, only for end-of-period reporting |
Automatic stop detection with mobile escalation is the single biggest lever on response time in most plants — bigger than any maintenance improvement. Cutting notification delay from 8 minutes to 1 minute on a line with 50 stop events per day recovers 350 minutes of production per day without any Kaizen work, any new tool, any new operator. The stops are not prevented; they are just responded to faster.
MTTR decomposition — the number that hides three numbers
Mean Time To Repair is the standard metric, and it is almost always reported as a single aggregate. That aggregate hides the three sub-metrics that are actually improvable. Decomposing MTTR is one of the exercises that consistently changes how a plant thinks about downtime.
MTTR = MTTD + MTTE + MTTFix
Mean Time To Detect + Mean Time To Engage + Mean Time To Fix
| Sub-metric | What it measures | Improvement lever |
|---|---|---|
| MTTD (Detect) | Time from stop to recognition that it is a stop | Automatic detection, tight thresholds |
| MTTE (Engage) | Time from recognition to responder present | Escalation architecture, mobile alerts, staffing |
| MTTFix (Fix) | Time from responder present to machine restart | Training, spare parts, standard work, TPM |
The shift-handover trap
The most expensive downtime minutes of the week are the ones that cross a shift boundary. A stop that begins at 13:55 and is still being diagnosed at 14:05 will almost always be handed over to the incoming shift — and handovers reset the clock. The new shift's maintenance person arrives with incomplete context, the outgoing operator has already left, and the diagnosis effectively restarts. A single downtime event can grow far beyond its expected duration purely because it crosses a handover.
This is not a maintenance problem and it is not a training problem. It is a data continuity problem. The fix is almost always the same: a shared digital shift log, tied to the same stop record that the MES is already tracking. The incoming team arrives with the cause, the diagnosis so far, the parts that were ordered, and the hypothesis that was being tested. The clock does not reset.
| Stop timing | Typical inflation vs. same stop mid-shift |
|---|---|
| Mid-shift stop | Baseline |
| Stop crossing single shift boundary | +40–80 % |
| Stop crossing Friday-evening / weekend boundary | +200–500 % |
The recovery tail — the loss that looks like performance
After every restart there is a period in which the machine runs, but not at nominal. Tools need to warm up, the first parts are inspected, process parameters stabilise. This "recovery tail" is universal and predictable — and in the classical OEE calculation it gets booked as a Performance loss, not as downtime. That categorisation is defensible, but it obscures the causal chain: the downtime event is the cause of the performance loss.
In plants with long-cycle, high-mass processes (forging, heat treatment, plastics), the recovery tail after a significant stop can be 15–60 minutes. A 20-minute repair that is reported as "20 minutes of downtime" may in reality cost 60–80 minutes of equivalent production. The only way to see this is to compare real output in the hour after a restart against the hour before a stop — a comparison that requires per-minute data, which requires automatic capture.
The true cost of one downtime minute
Every plant has an "official" cost per minute of downtime. In almost every case it is too low, because it only counts the direct contribution margin of the missed output. The honest calculation includes five layers:
| Cost layer | Usually counted? | Order of magnitude |
|---|---|---|
| 1. Lost contribution margin (missed output × margin) | Yes | Baseline |
| 2. Fixed-cost absorption shortfall (depreciation, salaries, overhead) | Rarely | +50–150 % |
| 3. Recovery-tail loss (first parts after restart) | Almost never | +10–40 % |
| 4. Quality risk on parts produced during unstable restart | Almost never | +5–20 % |
| 5. Expediting & downstream disruption (overtime, air freight, customer penalties) | Only for big events | Situational, can be multiples |
The fully loaded cost of a downtime minute in a typical automotive tier-1 plant is two to three times the number on the controller's dashboard. In packaging and FMCG it is usually even higher, because the recovery tail is longer. This matters not as a rhetorical point, but because the business case for response-time improvements scales linearly with this cost. A plant that doubles its cost-per-minute number (correctly) doubles the justified investment in Andon, MES and maintenance readiness.
Managing downtimes: the operational playbook
| Step | Action | Typical impact on total downtime hours |
|---|---|---|
| 1 | Automatic detection with PLC / I/O gateway — no manual logging | Reveals 20–40 % more downtime than previously reported |
| 2 | Escalation architecture with mobile alerts and clear ownership rules | –15 to –30 % on MTTE alone |
| 3 | Digital shift log tied to the live stop record | –30 to –60 % on shift-crossing stops |
| 4 | Standard work for the top 5 recurring stops (one-page playbook each) | –20 to –40 % on those stop types |
| 5 | Spare-part pre-positioning based on stop-frequency data | –10 to –25 % on long stops |
| 6 | Condition-based & predictive maintenance for bottleneck equipment | –5 to –15 % on unplanned events |
The common mistake is to start with step 6 — the most visible, the most capex-friendly, the most consultant-attractive. Predictive maintenance on a line with 8-minute notification delays and broken shift handovers will produce exactly the same availability as before, because the losses were never in the failure frequency. Steps 1–3 together routinely deliver more than steps 4–6 combined, at a fraction of the cost.
What the MES changes
| Without MES | With SYMESTIC MES |
|---|---|
| Stops noticed late, mean time to detect unknown | Stop detected automatically, PLC alarm attached |
| Escalation by walking, paging, SMS ad-hoc | Alarms by push or e-mail |
| Shift handover on paper — context lost | Digital shift log, open stops visible to incoming shift |
| MTTR a single monthly aggregate | MTTD, MTTE, MTTFix separated and trended |
| Recovery tail invisible, booked as performance loss | Per-minute output after restart visible and comparable |
| Cost per downtime minute theoretical, rarely updated | Actual lost output × real margin, per line, live |
FAQ
Is "downtime" the same as "downtimes"?
In casual language, yes. In operational practice, no. "Downtime" is an aggregate — the total minutes lost over a period. "Downtimes" is the set of individual events that make up that aggregate. The distinction is important because improvement levers act on events, not on totals. A plant with 300 short stops per day and a plant with three long stops per day may report the same total downtime, but they have completely different problems and completely different solutions. Any serious downtime programme starts by separating event frequency from event duration, and working on them as two separate problems.
Why does response time matter more than repair time?
Because in most plants response time is bigger, more variable, and more organisationally addressable. Repair time is a function of equipment design, spare-part availability and technician skill — all of which are slow and expensive to change. Response time is a function of notification architecture, escalation rules and staffing allocation — all of which can be improved in weeks, not years.
How should I think about planned vs. unplanned downtimes when setting targets?
Separately, always. Planned downtime is primarily a scheduling problem: are changeovers, maintenance windows and breaks efficiently timed and minimised? Unplanned downtime is primarily a reliability problem: are stops prevented, detected and resolved fast? Mixing them into one target encourages dysfunctional behaviour — plants that cut planned maintenance to hit a downtime target, and then pay for it with unplanned failures the following quarter. Best practice is two independent targets: one for planned-stop efficiency (SMED-style, on changeover and maintenance), one for unplanned-stop reduction (response and prevention). The OEE number aggregates them for reporting, but the improvement work has to stay separated.
How do I calculate the true cost of a downtime minute for my plant?
Start with the number on the controller's dashboard (contribution margin per unit × units per minute). Multiply by a factor that accounts for fixed-cost absorption — in most capital-intensive plants this factor is between 1.8 and 2.5. Add an allowance for the recovery tail — typically 10–25 % of the direct loss, higher in continuous processes. Add quality risk on restart parts where relevant. For bottleneck equipment, add the full downstream disruption cost because the plant cannot make up the lost output later. The resulting number is usually two to three times the standard calculation, and it is the correct basis for any investment decision on downtime reduction. A plant that cannot produce this number confidently is under-investing in response architecture, not over-investing.
Why do small downtimes matter when they are individually tiny?
Because they aggregate, and because they hide. A 90-second micro-stop is almost never logged manually, almost never escalated, almost never analysed. In high-cycle lines — packaging, assembly, electronics — 200 of these events per shift is normal. That is 5 hours of lost production per shift from events that individually feel too small to care about. A rule of thumb: the size of a plant's improvement opportunity is almost perfectly correlated with the size of the stops it is currently ignoring. Big stops get attention; the compound cost of small stops, invisible without automatic capture, is almost always the largest single bucket of avoidable downtime in the building.
Related: Machine Downtime · OEE · TPM · SMED · Production Costs · Lead Time · Alarms · MES
Calculate what a minute of downtime costs you
In a free 30-minute call we take your stops and their reasons and calculate their annual cost with your own numbers.
Know why the line stopped, not just for how long
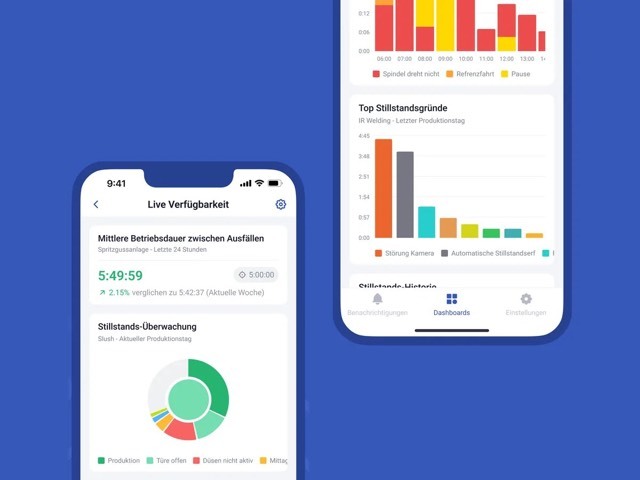
SYMESTIC detects every stop at the machine, and the operator picks the reason. Meleghy Automotive cut downtime by 10% with SYMESTIC.
−10%downtime
Automotive supplier cut downtime by 10%
Meleghy Automotive also raised output by 7%. Started on one press line, SYMESTIC ran in all four plants six months later.