


Contents
What is machine downtime?
Machine downtime is any period in which a machine scheduled to produce is not producing saleable output. It covers both unplanned stops (breakdowns, faults, material starvation, operator absence) and planned stops (changeovers, maintenance, inspections). Synonyms: machine stop, equipment downtime, Maschinenstillstand, Anlagenstillstand. In ISO 22400 terms it sits inside the Availability losses of OEE.
Downtime is measured against planned production time, not calendar time. The hard part is never the stopwatch — it's deciding what counts as a stop, who assigns the reason, and whether microstops under 60 seconds are logged at all. Get those three rules wrong and your downtime number looks fine while the line loses 20% of its capacity.
Machine downtime vs. microstops vs. planned downtime
Three terms that get mixed up in many reason-code taxonomies. They belong in different OEE buckets and trigger different corrective actions — confusing them is the fastest way to optimise the wrong problem.
Rule of thumb on the shop floor: if no one wrote down why it stopped, it was a microstop. That is precisely why microstops stay invisible — and why they're usually the biggest hidden loss.
What actually causes machine downtime?
Downtime causes cluster into five repeating categories across forging, beverage, assembly and plastics. Technical failures of mechanical, hydraulic or electrical components account for the largest share of unplanned downtime minutes in brownfield plants, usually bunched around aging drives, worn seals and PLC I/O modules. Material and logistics issues — empty upstream buffers, wrong material, late kit — contribute the next-largest share. Changeover and setup hide in plain sight: nominally planned, but the overrun is unplanned downtime. Operator-related stops (misoperation, breaks not covered, training gaps) make up a smaller share. Quality events — in-line rejects triggering stops, adjustments, re-feeds — close the loop back to COPQ. Any plant reporting only "other" or "technical" for more than 15% of stop time has a reason-code problem, not a maintenance problem.
How do you measure machine downtime correctly?
The formula is trivial: Downtime = Planned Production Time − Actual Running Time. The measurement is where it falls apart. Three rules for every rollout. First, the trigger comes from the machine, not from paper. A digital signal from the PLC — cycle pulse, safety circuit, spindle-run bit — defines running vs. stopped. Humans assign reason codes; they do not define the stop itself. Second, set a microstop threshold explicitly (60 or 120 seconds is standard) and log both sides separately. Third, reason codes belong in a two-level hierarchy: category (Technical, Material, Changeover, Operator, Quality) plus a specific code under it. Flat 40-item dropdowns get ignored. Once captured, downtime should feed straight into the Availability factor of OEE and into ISO 22400 KPIs like MTBF and MTTR without manual re-entry. If it's typed twice, it'll be inconsistent.
What does one minute of downtime actually cost?
Standard industry ranges put unplanned downtime at €2,000–€15,000 per hour in discrete manufacturing and considerably higher in automotive tier-1 lines under JIT obligations. A blunter number: take the contribution margin per part, multiply by the line's nameplate rate, that's your cost per minute. A 30-parts-per-minute assembly line with €4 contribution margin loses €120 every minute it's down. A forging press on a high-value part can burn €500+ per minute once you add scrap from restart transients. The hidden multiplier is downstream: one upstream stop creates a starved downstream line, a late delivery, a premium-freight shipment, and an angry customer scorecard. Quantified honestly, the business case for automatic downtime capture usually pays back within a few months.
How do you actually reduce unplanned downtime?
There is no single lever — there is a sequence. 1. Measure first. No initiative survives without a clean baseline. Connect the PLC, capture every stop automatically, let reason codes run for two to four weeks before changing anything. 2. Pareto the causes. In almost every plant, the top three reason codes account for 60–70% of unplanned minutes. 3. Fix the top two. Condition-based maintenance on the worst offender, process stabilisation on the second. Ignore the long tail until the top two are closed. 4. Industrialise the fixes. Move from reactive to preventive to predictive maintenance only where the data volume justifies it — most plants skip predictive and fail, because they never stabilised preventive. 5. Lock the gains. Visible dashboards at the line, shift-handover reviews tied to the same numbers, and reason-code discipline as part of the operator standard. That loop is what turns a downtime project into a downtime culture.
Hard-earned lesson from a Simatic S5→S7 retrofit on a beverage line: The customer reported low unplanned downtime and insisted their operators were meticulous. We tapped the PLC directly — no paper, no operator button — and captured every cycle pulse for two weeks. True unplanned downtime was several times higher. The delta was almost entirely sub-90-second stops caused by a chronically misaligned cap feeder that operators had learned to nudge back into alignment every few minutes. Each stop felt "not worth logging." Aggregated, it was the largest loss on the line. We didn't need predictive AI or a maintenance programme — we needed one inexpensive mechanical redesign of the feeder chute. Output rose noticeably in the following month. Principle: if downtime depends on human logging, you are measuring attention, not reality.
What this looks like in the SYMESTIC deployment pattern
We see the same pattern across 15,000+ connected machines: automatic capture first, reason-code hierarchy second, corrective action third. Carcoustics streams cycle and stop signals from 500+ machines. Klocke scaled to all Weingarten packaging lines in three weeks using plain digital-I/O gateways — no LAN retrofit required on older equipment. The deployment pattern is deliberately boring: tap the signal at the source, classify it with one taxonomy, and let the numbers do the arguing.
FAQ
What's the difference between machine downtime and idle time?
Downtime is a scheduled production period in which the machine is not producing. Idle time is unplanned but outside scheduled production — e.g., a shift with no order. Idle time sits outside OEE; unplanned downtime sits inside it as an Availability loss. Mixing them inflates OEE and hides real losses.
Is changeover considered downtime?
Technically yes — the machine isn't producing. Operationally, scheduled changeovers are usually treated as planned downtime and either excluded from OEE or tracked separately. Any overrun beyond the standard changeover target becomes unplanned downtime and should be flagged for SMED work.
What's an acceptable level of unplanned downtime?
In world-class discrete manufacturing, unplanned downtime sits below 5% of planned production time. Mid-maturity plants land at 10–15%. Over 20% is a signal that measurement, maintenance strategy or material supply is structurally broken — not that operators need more training.
How does downtime relate to OEE?
Unplanned downtime directly reduces the Availability factor of OEE. A line running 6 hours unplanned-stopped out of a 16-hour scheduled shift has 62.5% Availability before Performance and Quality are even applied. Reducing downtime is usually the single biggest lever on OEE.
Can old machines without modern controls be monitored for downtime?
Yes, always. A digital I/O gateway wired to a single "machine running" signal — often already present as a lamp, relay or contactor — captures runtime and stops without any PLC programming change. The machine doesn't need to be smart, the gateway does.
How long does it take to implement automatic downtime tracking?
On a single line with a modern PLC (S7 / TIA), 2–4 hours per machine for the gateway, plus configuration. A full plant of 20–40 machines typically takes 2–4 weeks end-to-end, including reason-code taxonomy workshops. Brownfield plants with mixed controls take longer on taxonomy than on technology.
Why does manual downtime logging fail?
Because operators are paid to run the line, not to document why it stopped. Under 60-second stops are almost never logged. Reason codes get approximated. By shift end, memory has overwritten detail. Manual logging typically under-reports downtime substantially. It's not dishonesty — it's human bandwidth.
How does SYMESTIC track machine downtime?
SYMESTIC taps machine signals via OPC UA, digital I/O or MQTT gateways, auto-detects every stop above a configurable microstop threshold, and prompts operators to assign reason codes from a two-level taxonomy on the shop-floor client. Data flows live into Production Metrics dashboards and into Alarms when PLC-level events are correlated. Go-live on a line is typically days, not months.
Related: OEE · MES · MTBF · MTTR · Predictive Maintenance · Cost of Poor Quality · Machine Data Capture (MDE) · Alarms · Production Metrics · OEE Software.
Calculate what your machine downtime costs
In a free 30-minute call we take your stops and their reasons and calculate their cost per year with your own numbers.
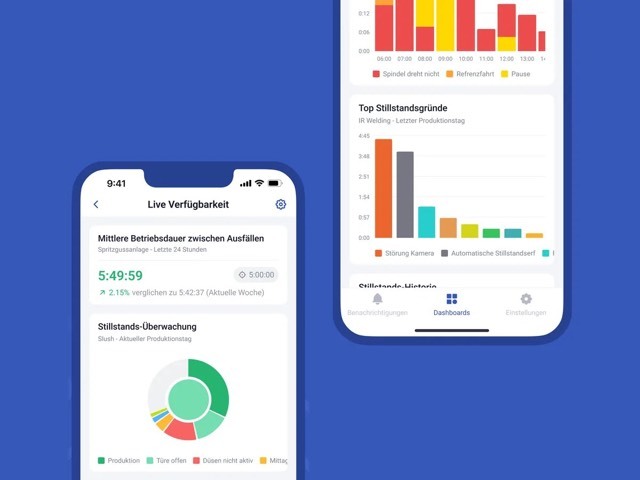
Know why the line stopped, not just for how long
SYMESTIC detects every stop at the machine, and the operator picks the reason. Meleghy Automotive cut downtime by 10% with SYMESTIC.
−10%downtime
Automotive supplier cut downtime by 10%
Meleghy Automotive also raised output by 7%. Started on one press line, SYMESTIC ran in all four plants six months later.