




Contents
TL;DR: Planned Maintenance Percentage (PMP) is the share of total maintenance hours that were scheduled in advance: planned maintenance hours ÷ total maintenance hours × 100. The number on its own tells you very little. What matters is how the underlying hours were booked, and whether the classification survives a serious audit.
What is Planned Maintenance Percentage?
Planned Maintenance Percentage (PMP) is a maintenance-performance KPI that measures the proportion of maintenance work which was scheduled — by date, by runtime counter, by condition trigger or by prior work order — against the total maintenance effort in a given period. It is one of the most widely used indicators of maintenance maturity, sitting alongside MTBF, MTTR and availability as the standard vocabulary for how well a plant manages its equipment.
The metric exists because maintenance cost does not behave linearly. An hour of planned work during a scheduled window is not the same cost as an hour of unplanned repair during production — the unplanned hour carries lost output, expedited parts, overtime labour and the collateral damage of an unscheduled stop, which the planned hour does not. PMP captures that asymmetry in a single ratio. High share of planned work means the maintenance organisation is in control of its schedule. Low share means the schedule is in control of the maintenance organisation. The unplanned share is corrective maintenance.
How is PMP calculated?
The formula is simple; the bookkeeping behind it is where all the interesting questions live.
PMP = (Planned maintenance hours ÷ Total maintenance hours) × 100
Worked example. A plant records 480 maintenance labour hours in a month. 360 of those hours came from scheduled work orders — preventive maintenance tasks, planned component swaps, condition-triggered interventions that were queued and dispatched in advance. 120 hours came from break-in work: a bearing failure on a press, an unexpected hydraulic leak, a sensor fault during night shift. PMP = (360 ÷ 480) × 100 = 75%. Three of four maintenance hours were scheduled in advance.
The arithmetic is not the problem. The problem, as anyone who has spent time in a maintenance meeting knows, is the numerator. What counts as "planned"? A work order raised at 8:00 and executed at 10:00 the same morning — is that planned? What about a stop triggered by condition monitoring that the team knew about for two shifts before acting on it? What about the five-minute adjustment that the day-shift technician does three times a week and nobody books at all? Every plant answers those questions differently. Every answer changes the number.
How do you read a PMP value?
No published range for PMP holds across plants, because the number depends on how "planned" is defined and how the hours are booked. A plant that allows retroactive classification will always report higher values than one that requires a work order raised before the work started, and the two values do not mean the same thing. The table therefore describes maturity by what the shop floor looks like, not by percentage bands.
The step from a middle to a high PMP is real work: it needs disciplined PM execution and fewer unplanned failures. Beyond that, further gains in the number are more often changes in how the hours are booked than better maintenance. That is why PMP has to be read together with MTBF and availability.
Where does PMP reporting typically go wrong?
Four bookkeeping patterns recur when PMP looks better than the production reality suggests. None of them is fraud. All of them are conventions that drift in a convenient direction when nobody is watching.
- Retroactive work orders. A line goes down at 03:00. A technician fixes it by 04:30. At 09:00 the next morning, a work order is raised dated 02:00 — "planned inspection." The hours flow into the planned bucket. Technically the CMMS shows a work order that preceded the work. Practically, it was a break-in fix. The fix: enforce work-order creation timestamps at the BDE/MDE layer, not in the CMMS UI where they can be backdated.
- Duration inflation of planned jobs. A planned PM task scheduled for two hours runs over because a component was unexpectedly worn. The extra three hours should logically split — two planned, three unplanned. In practice the whole five hours usually gets booked as planned because "the work order was a PM." This is a frequent distortion in PMP and hard to fix without changing how technicians log time.
- Denominator erosion. Small unplanned interventions — the five-minute jam clear, the reset of a conveyor fault, the operator's lubrication top-up between shifts — are often not logged at all. They don't appear in the numerator (they weren't planned) and they don't appear in the denominator (they weren't logged anywhere). PMP looks cleaner than it is because the messy hours are invisible.
- The "standing work order" trick. A permanent, open work order labelled "routine maintenance" absorbs any hours the technicians cannot otherwise classify. Everything in that bucket is planned by definition. This makes PMP look better on paper than the shop floor runs.
The pattern behind all four: PMP is assembled from two numbers that humans fill in, and whenever humans fill in numbers under management attention, the numbers drift toward the preferred answer. The only durable counter is automation of the capture layer — machine states, stop reasons and durations written directly from the PLC or the I/O gateway into the MES, then reconciled against the CMMS work order. The shop floor can still argue about classification, but it can no longer argue about how long the machine was down.
How does PMP relate to PM Compliance, MTBF and availability?
PMP is one indicator in a family, and reading it alone produces the wrong conclusions. The useful cross-check is always the triangle below.
The healthy signature of a maintenance program that is genuinely improving: PMP rises, PM Compliance stays high, MTBF rises, availability rises. The signature of a program that is only improving on paper: PMP rises, PM Compliance rises to implausibly perfect levels, MTBF flat or falling, availability flat. Any plant management review that looks at PMP without MTBF next to it is reading half the page.
How do you actually improve PMP?
Real PMP improvement — the kind that also moves MTBF and availability — follows a predictable sequence. The theoretical version is in every maintenance textbook. The practical version is shorter and less elegant.
- Fix the capture layer first. Before trying to move the number, make sure the number is honest. Automatic downtime capture through the PLC or an I/O gateway, classified by the operator with a short reason code, timestamps written into the MES. Until stop reasons are captured automatically, every discussion about PMP is a discussion about gut feel.
- Define "planned" and write it down. One page. A work order raised and released before the intervention started. Signed by maintenance and production. Anything else is unplanned. This sounds obvious and is almost never done explicitly, which is why the number drifts.
- Pareto the unplanned hours. A Pareto of the unplanned hours shows which few failure modes account for most of the time lost in your plant. Attack those first — with condition monitoring, with redesigned PM intervals, with root-cause fixes that eliminate the failure rather than treat it. Each failure mode eliminated shifts hours from the unplanned to the planned bucket honestly.
- Raise PM Compliance before raising PMP. A plant that executes its scheduled PM tasks on time and to spec will see PMP rise naturally as MTBF improves. A plant that tries to raise PMP while PM Compliance is low is optimising the wrong variable.
- Audit the classification boundary quarterly. Pull a random sample of 20 work orders from the last month. Check the timestamp of work-order creation against the timestamp of the stop event in the MES. Any work order created after the stop started is unplanned, regardless of what the CMMS says. This single check, done honestly, keeps the number connected to reality.
Where does PMP fit in the SYMESTIC platform?
SYMESTIC is not a CMMS. Work orders, maintenance plans and maintenance hours stay in the CMMS — SAP PM, IBM Maximo, Ultimo and similar. What SYMESTIC contributes is the production side: stops and their reasons recorded per machine, alarms and fault messages sent to maintenance by push or email, and MTBF and MTTR as key figures. Stops are recorded automatically, via OPC UA through the Cloud Gateway (software that runs on your own server or PC) or, for digital signals from older machines, through the IoT Box (hardware). The data can be handed to the maintenance software over the REST API, so the stop timestamps are available when a work order's classification is checked against what actually happened. For further reading, the relevant frameworks are EN 13306 (maintenance terminology) and VDI 2895 (organisation of maintenance). The related KPIs are explained under planned vs. reactive maintenance.
FAQ
What is a good PMP target?
There is no universal target. A target means something only once "planned" is defined strictly (a work order raised and released before the work starts) and PMP is read together with MTBF and availability. Set the target against the plant's own baseline measured under that definition, and check that MTBF and availability move with it. A value that rises very fast or sits near 100% should be audited before it is celebrated: it may reflect classification conventions more than maintenance excellence.
Is higher PMP always better?
No. A PMP that rises while MTBF stays flat means the maintenance organisation is doing more planned work without preventing more failures — which is over-maintenance, not excellence. A PMP that rises together with MTBF and availability is the healthy signal. Always read the three together.
What is the difference between PMP and PM Compliance?
PMP is a ratio of hours: planned maintenance hours ÷ total maintenance hours. PM Compliance is a ratio of tasks: completed PM tasks ÷ scheduled PM tasks, measured in a defined due-date window. They answer different questions. PMP tells you how much of your effort was scheduled. PM Compliance tells you whether you actually did what you scheduled. A plant can have high PMP and low PM Compliance if it reclassifies break-in work as planned while skipping the actual PM schedule — that combination is common and worth checking for.
How is "planned" maintenance defined in practice?
The only workable definition is a work order raised and released before the intervention starts, with a timestamp that pre-dates the stop event. Any looser definition — "we knew about it a while ago," "it was in the plan" — is unenforceable and drifts toward whatever makes the number look best. Tighten the definition and the number becomes meaningful; leave it loose and the number becomes theatre.
Does PMP apply to condition-based maintenance?
Yes, and arguably more cleanly. A condition-monitoring alert that triggers a work order, which is then scheduled and executed before failure, is by any reasonable definition planned maintenance — even though the trigger was reactive to a sensor signal rather than to a date. The more condition-based maintenance a plant runs, the more naturally PMP rises, because the window between "we know this is coming" and "we fix it" expands.
Why does PMP drop when we install MES-based downtime capture?
Because the previous number was wrong. Automatic capture catches the small unplanned interventions that manual logging missed — the five-minute jam clears, the shift-handover fixes, the night-shift resets that nobody wrote down. Those hours appear in the denominator, PMP drops, and the new baseline is the first honest number the plant has had. From there, real improvement is measurable. Without that step, every subsequent improvement claim is unverifiable.
How often should PMP be reviewed?
Monthly at maintenance-manager level, quarterly at plant-manager level, with a deeper classification audit once per quarter. Weekly tracking is usually overkill — PMP is a trend metric, not an operational one. What matters is that the review includes MTBF and availability on the same page, and that the classification boundary is audited periodically against actual stop-event timestamps from the MES.
Related: Preventive Maintenance · MTBF · MTTR · Availability · Condition Monitoring · CMMS · Machine Data Acquisition · OEE · Manufacturing Operations Management · Alarms.
Put a euro value on your unplanned maintenance hours
In a free 30-minute call we compare planned and unplanned stops and calculate what the unplanned share costs you per year.
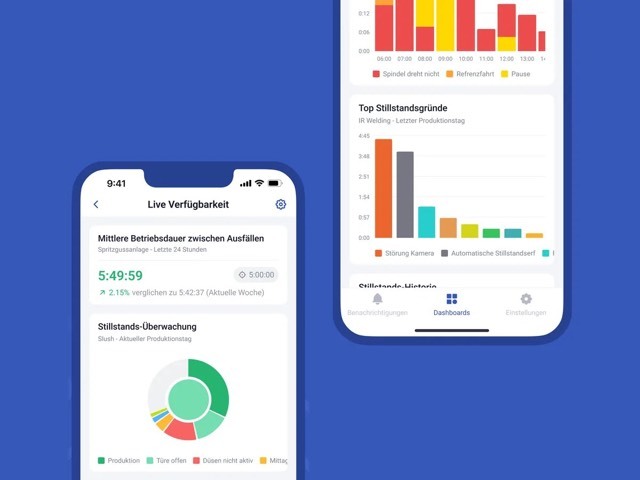
Know why the line stopped, not just for how long
SYMESTIC detects every stop at the machine, and the operator picks the reason. Meleghy Automotive cut downtime by 10% with SYMESTIC.
−10%downtime
Automotive supplier cut downtime by 10%
Meleghy Automotive also raised output by 7%. Started on one press line, SYMESTIC ran in all four plants six months later.